 system-one-bench
Limits and caveats
What was tested, what was found and with what certainty — schemas, thinking, modes and option order. Measured on Qwen3.8-27B via the LLM adapter (except DiffusionGemma in §8). Summary on the home page.
Subject of this page. Almost every figure comes from Qwen3.8-27B, an open-weight generalist LLM scored via the llm adapter (system-one-adapter, TypeSafe contract)—not a dedicated decider like Jev/Clef. The pre-registered confirmatory session (hypotheses §2, cells §5) is local FP8 (SGLang). The bars in §6–§7 add the same questions under NVFP4, GGUF, and, where noted, the Cerebras API—same model, different quant or host. Schema non-injection (§3–§4) was also probed on llama.cpp, vLLM 0.29.0 and Ollama 0.32.14. The only other-model row is DiffusionGemma in §8 (rotation), shown separately on purpose.
1. Map of the experiment
What is changed, what is measured and where each finding lives. The adjusted subtracts the majority baseline: 0 = doing the same as always answering the majority class; high values = real improvement over that trivial floor.
Four variables: schema visibility, probability or discrete mode, thinking and option order. The measured metric is the adjusted score with reference 0 equal to the majority. Findings: blindness, hypothesis forest, tokens, modes and rotation.
Short glossary (bench terms)
- Adjusted
- Accuracy points above (or below) the majority class. 0 = no better than the trivial floor.
- Visible / inject
- The typed questions are copied into the system prompt. Without that, on several local servers Qwen3.8-27B answers blind.
- Blind (struct without inject)
- Schema forced only as output grammar; the questions do not appear in the text the model reads.
- probabilities / discrete
- The adapter's two output modes (distributions vs a discrete choice). They change prompt and format at once.
- Thinking
- The model's reasoning chain turned on or off.
- F0–F3 / T0–T1 / D0–D1 / DT
- Session cells: F = probabilities without thinking (orders d0–d3); T = with thinking; D = discrete without thinking; DT = discrete with thinking (JEV-76 session, which repeats F/T/D as fresh controls; ′ marks that session's control).
- pp
- Percentage points (a difference of percentages, not adjusted points).
- Canary
- Behavioural test: it only hits the correct label if it reads its description. Observational; visibility is accredited by tokens + the blind control.
- CONFIRMED / INCONCLUSIVE / REFUTED
- Verdict against the pre-registered threshold and its confidence interval — not "there is/is no effect" in the abstract.
2. Pre-registered hypotheses: estimate, CI and verdict
Each row is a hypothesis with a threshold fixed before running. The dot is the estimate; the horizontal bar, the confidence interval; the dashed line, the threshold. The badge is the verdict (colour and text). INCONCLUSIVE ≠ "no effect": the CI does not cross the threshold the required way.
Thinking original order T0 minus F0: estimate +11.69, 97.5 % CI [−0.28, +28.04], threshold ≥ +5, INCONCLUSIVE. Thinking rotated order T1 minus F1: +6.51, 97.5 % CI [−1.97, +16.58], threshold ≥ +5, INCONCLUSIVE. Stability range F0 to F3: 9.62, 95 % CI [4.58, 17.55], threshold ≤ 5, INCONCLUSIVE. Primacy bronchoscopia: +35.14 pp, 95 % CI [16.67, 52.78], threshold ≥ +5 pp, n=37, CONFIRMED. Discrete minus F0: +12.85, 95 % CI [3.11, 24.94], threshold ≥ +10, INCONCLUSIVE. Replica S202: 253 of 255 (99.22 %), 95 % CI [97.2 %, 99.9 %], threshold ≥ 97 %, CONFIRMED. Anti-injection V3: −1.11 pp, 97.5 % CI [−3.33, 0], threshold ≥ +10 pp, n=12, REFUTED. Anti-injection V5: −2.22 pp, 97.5 % CI [−8.89, 0], threshold ≥ +10 pp, n=12, REFUTED.
Exact figures from the «Pre-registered classification» table of the session's results manifest (2026-10-07). F0–F3 range mean: 52.19. Primacy errors d0/d1/d2/d3 = 22/9/15/24 out of 37.
The JEV-76 session (Oct 7) completes the factorial with the missing cell — discrete + thinking (DT) — and repeats F/T/D as fresh controls in both orders (8×194 cases, same GT v4 battery). Four primary contrasts, all with the same ≥ +5 threshold and 98.75 % CI (Bonferroni for a 95 % family coverage).
Thinking over discrete, original order, DT0 minus D0′: estimate −3.48, 98.75 % CI [−11.39, +3.62], threshold ≥ +5, REFUTED. Thinking over discrete, rotated order, DT1 minus D1: −5.58, 98.75 % CI [−14.82, +2.59], threshold ≥ +5, REFUTED. Discrete vs prob with thinking, original order, DT0 minus T0′: +0.85, 98.75 % CI [−5.19, +6.75], threshold ≥ +5, INCONCLUSIVE. Discrete vs prob with thinking, rotated order, DT1 minus T1′: −8.65, 98.75 % CI [−18.09, −1.94], threshold ≥ +5, REFUTED.
The four rows share the scale (−20 to +10; formula in the chart's source), so the +5 threshold falls on the same x. H1's CIs include zero: neither degradation nor equivalence demonstrated. Exact figures from «Pre-registered classification» in docs/infra_runs/qwen38_jev76.md §RESULTADOS (session s81f-20261007-0800; 1,552/1,552 cases, 0 errors). Descriptive interaction (outside the confirmatory family): ≈ −12.1 points in both orders.
3. How the questions reach the model
With structured output, the adapter sends the system prompt and the document in the chat. The typed questions travel in response_format (JSON Schema). If the server does not copy that schema into the prompt, the model answers blind — it only uses the schema as the grammar of what it can write. On this page the measured subject is Qwen3.8-27B; the list names servers where non-injection was observed.
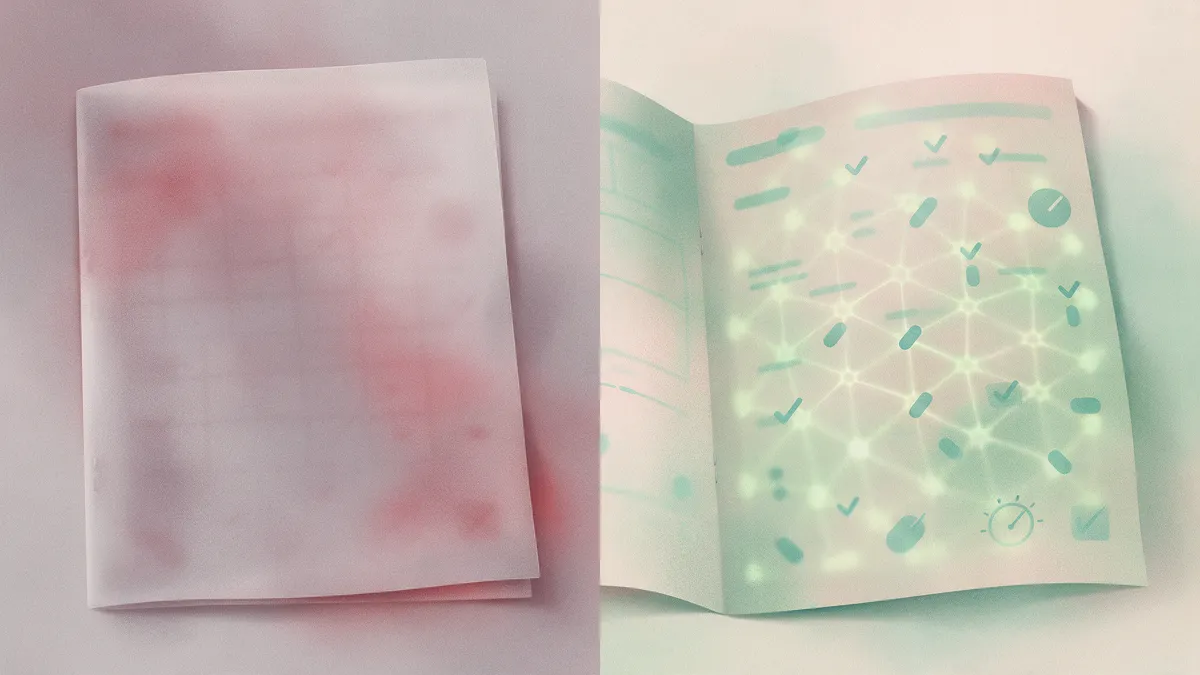
Two columns. Before: TypeSafe probabilities prompt without questions in the system, schema as grammar only; Cerebras does inject, several local servers do not. After: inject copies the schema into the system prompt; the model sees the questions.
Measured local mitigation: copying the schema into the system prompt while keeping the grammar. Upstream proposal: system-one-adapter#50.
4. Token probe (visibility)
Same request, same case: if the questions are in the prompt, there are many more input tokens. Operational gate: visible − blind ≥ 200 tokens, plus a blind control. The behavioural canary (choosing a label only if its description is read) remains an observation: under structured grammar the label's name can give it away by chance.
Horizontal bars: blind around 222 tokens; visible with inject around 806. Difference 584, above the 200 threshold.
On Cerebras the measured contrast was ~222 local versus ~958 with provider injection (same idea: visible questions).
5. Adjusted score per cell (FP8 session)
Seven cells from the same local session (struct+inject, GT v4, 194 cases). Axis from majority = 0: further right = better than the trivial floor. No per-cell CIs on this chart (the forest above carries the hypothesis CIs).
Bars: no thinking original order 49.57; rotated order 58.41; d2 51.97; d3 48.80; with thinking d0 61.26; with thinking d1 64.92; discrete 62.42.
6. Effect of blindness on the adjusted score
When Qwen3.8-27B does not see the questions, the adjusted score falls below the majority (negative). With visible questions it returns to the ~48–52 band. That explains the trivial floor; it does not close the gap versus the same model on Cerebras (59–66). Descriptive comparison (not a single-variable ablation); no CIs on these scoreboard bars.
Historical blind minus 15 asterisk GT v4; inject FP8 51; NVFP4 50; GGUF 48; without forced schema NVFP4 52.
7. Discrete versus probabilities
With visible questions, discrete mode raises the adjusted score versus probabilities on the local backends measured for Qwen3.8-27B (NVFP4/GGUF). The mode changes prompt and format at once; on Cerebras the sign flips. Here: scoreboard figures, no CIs (the forest §2 carries the CI of discrete−F0 on FP8: +12.85 [3.11, 24.94], threshold +10 → INCONCLUSIVE).
Pairs: NVFP4 probabilities 50 versus discrete 63; GGUF 48 versus 63.
8. Sensitivity to option order
Rotating the order of the choice options moves the accuracy even though the content is the same. They are not the same experiment or the same model: they are shown separately. Only DiffusionGemma publishes a CI95 on this figure; Qwen A3 is a point Δ with no CI here (primacy with a CI is in the forest §2).
Qwen A3 plus 6.2 percentage points with no confidence interval on this figure. DiffusionGemma Rot1 minus 7.4 with a CI95 from minus 11.9 to minus 3.1 (GT v4).
9. Fix expected in the adapter
With structured=true, the questions should be injected into the prompt when the server does not do it on its own. Evidence packaged in the upstream issue:
← Back to the recommended circuit · Methodology: LLM adapter